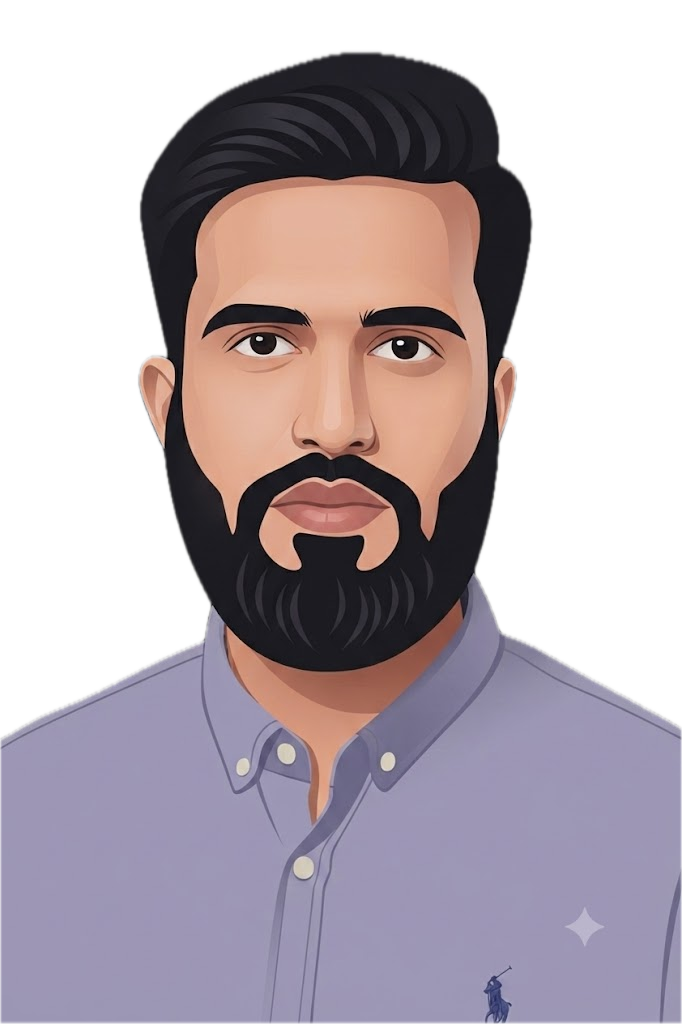
Hamza Awan
DevOps · SRE · Cloud & Platform Engineer
Hamza Awan is a freelance DevOps, SRE, and Cloud/Platform engineer who designs and operates CI/CD pipelines, cloud infrastructure, Kubernetes platforms, and observability systems for founders, CTOs, and engineering teams who need production-grade reliability without hiring a full ops team.
I make infrastructure boring — pipelines that deploy themselves, dashboards that catch problems first, and a product that just stays up while you sleep.
Good infra is invisible.
Bad infra pages you
at 3am.
Infrastructure only gets noticed when it breaks — a deploy that needs a prayer, an alert that fires at 3am and means nothing. I’m a DevOps/SRE contractor who builds the version nobody notices: CI/CD pipelines, cloud infrastructure, container orchestration, and monitoring that means something when it fires.
Founders and CTOs usually bring me in when production depends on tribal knowledge and manual steps. I leave behind the opposite — automated deploys, infrastructure as code, dashboards worth trusting — run by your own engineers, not by me forever.
- 6+
- Yrs Engineering
- 50+
- Projects
- 15
- Clients
- 99.9%
- Uptime
- 60%
- Cost Saved
- 100%
- Delivered
Version-controlled everything
If it's not in a repo, it doesn't exist in production. Infrastructure is code — it gets reviewed, tested, and tracked.
Design for failure
Systems break. The goal is predictable failure modes, fast recovery, and no surprises at 3am.
Build for the handover
Good infrastructure can be handed to the next engineer without a week of undocumented context.
Observe before you trust
If you can't measure it, you don't know it's working. Metrics, logs, traces — baked in from day one.
What I ship.
Five layers of the same system — each one feeding the next.
Cloud Infrastructure
AWS, GCP, and Azure environments designed for multi-region resilience. IAM architecture, VPC design, cost governance, and disaster recovery built into every deployment.
CI/CD & GitOps
Pipelines that test, scan, sign, and deploy with full observability and rollback at every stage. GitOps where it fits; pragmatic automation where it doesn't.
Container Orchestration
Kubernetes that your team can operate, not just deploy to. RBAC, namespace isolation, admission controls, and internal tooling so ops isn't the bottleneck.
Observability
Full-stack monitoring with metrics, logs, and distributed traces. Dashboards that tell the truth and alerts that page for the right reasons — baked in, not bolted on.
Reliability Engineering
SLI/SLO definition, error budget management, and on-call hygiene. Moving teams from reactive firefighting to systems that fail predictably and recover automatically.
Tech arsenal.
The tools I reach for when infrastructure needs to be production-grade.
 AWS
 Google Cloud
 Azure
 DigitalOcean
 Terraform
 Ansible
 Packer
 HashiCorp Vault
 Kubernetes
 Helm
 Docker
 Istio
 GitHub Actions
 ArgoCD
 Jenkins
 Tekton
 GitLab CI
 Prometheus
 Grafana
 OpenTelemetry
 Datadog
 Bash
 Python
 Go
 HCL
 YAML
 Linux
The work.
Selected projects — case studies on request.
Trusted in production.
Founders and engineering leads bring me in when production can’t afford to be down. Here’s what they said afterwards.
Certified, not claimed.
The certifications behind the work — each independently verifiable at the issuer.
- Verify
AWS Certified Cloud Practitioner
IDe8df7b40-304d-4e38-a161-821bec70df6c
Writing.
Infrastructure opinions, field notes, and honest postmortems.
Happy 20th Birthday, AWS EC2: The Server That Changed Software Forever
EC2 turned 20 on August 25, 2026. A practitioner's retrospective on how a $0.10/hr beta in 2006, built by 14 engineers in Cape Town, rewired the software industry. From m1.small to Graviton5 and 39 global regions.
Read article"DevOps Engineer" Is Dead. Here's the New Title You Need on Your Resume by Friday
Platform Engineer, SRE, MLOps, the 2024-2025 salary data shows which title pays more and lands interviews faster. Backed by Kube Careers, DORA 2024, and the State of Platform Engineering survey. Here's the exact framework to update your resume this week.
Read articleWhy You Need a Multi-DNS Provider Strategy (Lessons From the 2025 AWS and Cloudflare Outages)
DNS is the quiet single point of failure that most of the internet still bets everything on. Two 2025 outages proved the cost: on October 20 a DNS fault inside AWS us-east-1 cascaded across the internet for about 15 hours, and on November 18 Cloudflare, a provider that runs DNS for millions of domains, went dark for roughly six hours. Neither shared a cause, but both teach the same lesson: if every name your service depends on resolves through one provider, that provider is your outage.
Read articleReady to build
infrastructure
that lasts?
Platform buildouts, infrastructure audits, embedded SRE, and DevOps consulting. I work with product teams who need production-grade reliability without assembling a full ops team.
Frequently asked.
Cloud infrastructure, CI/CD and GitOps pipelines, Kubernetes/container orchestration, reliability engineering (SLOs, on-call, incident response), and observability — plus platform buildouts, infrastructure audits, and embedded SRE work.
AWS, GCP, and Azure for cloud; Terraform, Ansible, and CloudFormation for infrastructure as code; Kubernetes, Helm, and Istio for orchestration; GitHub Actions, ArgoCD, and Tekton for CI/CD; and Prometheus, Grafana, Loki, and OpenTelemetry for observability.
Yes — he's available for contract engagements, remote-first, with a response time within 24 hours.
Fixed-scope or time-and-materials, depending on the work. No vendor lock-in — infrastructure and processes are handed off to your own team, not run indefinitely by him.
Both. Engagements range from infrastructure audits and short buildouts to embedded SRE and ongoing DevOps consulting, depending on what the team needs.
6+ years of hands-on experience in engineering and production infrastructure.
Let’s build
something real.
Available for infrastructure engagements, platform audits, and DevOps consulting.
- LocationDubai, UAE
- Phone+971 55 398 6475
- Email[email protected]